Overview
This document outlines recommended steps and considerations for upgrading from RPI v7.7 to v7.8. In addition to this topic, be sure to also review the RPI v7.8 release notes.
If you’re upgrading from a version earlier than RPI v7.7, there are some additional considerations. If you are upgrading from…
-
RPI v7.6, also refer to Upgrading to RPI v7.7: Helm chart updates.
-
RPI v6.x, also refer to Upgrade to RPI v7.x.
Develop a client-specific MoP/SoP (recommended)
Because client environments and connector configurations vary, we strongly recommend developing a client-specific Method of Procedure (MoP) or Standard Operating Procedure (SoP) to standardize upgrade execution.
We recommend creating a documented procedure that includes:
-
Estimated timing and ownership of each step
-
Pre-upgrade shutdown steps
-
Validation checks
-
Rollback criteria and decision points
Executing the same procedure for each upgrade reduces operational variance and risk.
Before you begin: pre-flight checks
Complete these checks on your overrides file before you deploy anything. The first two describe conditions that are not reported as configuration errors at deploy time: the first stops services from starting, and the second changes send throughput without any warning.
Check for a removed cache provider value
If any environment still sets InternalCache__StatePersistence__Provider to DefaultCache, the Execution Service and Queue Reader will fail to start on v7.8. DefaultCache was removed from the provider list, and an unrecognized value causes service startup to fail rather than falling back to a default.
The RPI v7.8 Helm chart defaults this setting to FileSystem, so most deployments are unaffected. You only need to act if your own overrides, secrets, or environment variables set the value explicitly.
Search every overrides file, values.yaml, secret, and environment-variable source for DefaultCache. If you find one, change it to FileSystem or AzureBlobStorage before you deploy.
Check for a renamed LuxSci throughput setting
Plugins__LuxSci__SendRequestCount was renamed to Plugins__LuxSci__MaxConcurrentApiRequestsPerAccount in v7.8. The old name binds to nothing and is ignored silently, so a throughput cap set under the old name is lost without any error, which can result in an unintended change in concurrency on large LuxSci sends.
The v7.8 Helm chart already uses the new name. You only need to act if you set this environment variable directly rather than through the chart. If so, rename it, and optionally set maxDegreeOfParallelism alongside it. The defaults are 5 and 10, respectively.
Remove the RedpointAI vector search values
redpointAI.VectorSearchProfile and redpointAI.VectorSearchConfig have been removed. RPI now creates the search index, vector profile, and algorithm dynamically at runtime. Remove both from your overrides file before upgrading.
Housekeeping (optional)
InternalCache__BackupToOpsDBInterval and InternalCache__FailOnPrimaryDataLoss were removed in v7.8 along with OpsDB-backed cache failover. They are ignored rather than rejected, so a stale override is harmless, but you may want to remove them from the Execution Service and Queue Reader configuration while you are in the file. They do not appear in the v7.8 Helm chart.
Step 1: Establish an upgrade window
After reviewing all of the upgrade requirements and process, estimate a downtime window, making sure to not attempt to upgrade during live execution.
Step 2: Back-up databases & prepare for potential rollback
Rollback planning should be defined before upgrade execution.
Prior to upgrade:
-
Perform full backups of:
-
RPI operational databases (Ops DB)
-
RPI Offer History tables. Create individual backups of these tables prior to upgrading and be prepared to replace data in the original tables from the backups if a rollback is required. Individual table backups would likely be copies of the tables with a suffix such as
_bak_yymmddor similar. -
Campaign data warehouses (optional)
-
-
Ensure Point-in-Time Restore (PITR) is enabled where supported (e.g., Azure SQL, Cloud SQL, Amazon RDS)
This backup serves as the rollback anchor if restoration of v7.7 becomes necessary.
The individual Offer History table backups matter particularly in v7.8, because this release adds columns to those tables: a new column is added to offer history and audience contact tables on first use, and the Audience Validation task in Step 8 adds the IterationNumber column. Columns added during or after the upgrade are not removed by rolling the binaries back.
Rolling back to a previous version carries the risk of data loss. Refer to Rollback considerations at the end of this topic for what specifically does not roll back.
Step 3: Schedule Maintenance Mode
RPI’s Maintenance Mode simplifies preparation for the upgrade by programmatically disabling workflows and non-cluster admin users and allowing you to schedule the maintenance window.
How Maintenance Mode disables workflows and user access
Workflows
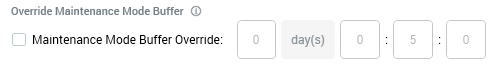
To prevent new workflow activities from starting as a scheduled Maintenance Mode window approaches, you’ll need to specify the buffer, which is the amount time prior to scheduled maintenance to place any interaction workflow activity into a Queued status.
Ideally, the buffer time should be long enough to cover the expected time to execute an offer activity to avoid pausing the offer activity during the upgrade. You can do one of the following:
-
Modify the buffer time prior to using Maintenance Mode with
executionservice.defaultMaintenanceModeBufferTimeinvalues.yaml(environment variableRPIExecution__DefaultMaintenanceModeBufferTime). Note, however, that modifying this setting requires redeploying the app. -
Accept the default of 5 minutes (
"00:05:00") and modify the setting at a later point for future upgrades. Keep in mind that you’ll be confirming that no workflows are running before proceeding with the upgrade. -
In addition, this can be overwritten at specific triggers.
Users
When the Maintenance Mode window begins, all users (except for cluster admin users) are logged out of the system and unable to log in for the duration of the maintenance window. You can configure a message to be displayed when unauthorized users attempt to log into the client.
Step 3a: Schedule a Maintenance Mode window
Schedule a Maintenance Mode window ahead of the upgrade using the Configuration Service API (Set Maintenance Mode Schedule). For example:
DEPLOYMENT_SERVICE_URL=<prefix>-deploymentapi.<domain>
CLIENT_ID=<my RPI tenant client id>

curl -X POST "https://$DEPLOYMENT_SERVICE_URL/api/maintenance/maintenancemode/schedule" \
  -H "Content-Type: application/json" \
  -d '{
    "ID": "$CLIENT_ID",
    "StartDate": "1970-01-01T00:00:00.000Z",
    "EndDate": "1970-01-01T00:00:00.000Z",
    "StartTime": "00:00:00.000Z",
    "EndTime": "00:00:00.000Z",
    "Mode": "Single",
    "Days": [
      "Sunday"
    ],
    "DaysOfMonth": [
      0
    ],
    "Message": "string",
    "IsDeactivated": false
  }'
-
Times are based on the pod clock times.
-
You can modify the maintenance window duration, if needed, using the same endpoint.
Step 3b: Confirm that no workflows are running
Run the following query until there are no more records returned, indicating all running activities are complete, and you are ready to proceed.
SELECT
    (SELECT COUNT(*)
     FROM dbo.rpi_ExecutionSchedule
     WHERE ExecutionStatus = 'Running')
  +
    (SELECT COUNT(*)
     FROM dbo.rpi_Tasks
     WHERE IsRunning = 1) AS TotalRunning;
Step 4: Disable workflows
Although Maintenance Mode gracefully stops your workflows for the specified buffer time, to make sure that workflows won't start again immediately after the buffer ends, we recommend that you additionally disable active workflows programmatically. You’ll re-enable them once you’ve validated the upgrade.
Step 5: Update the Helm chart (self-hosted deployments)
In RPI v7.7, the Helm chart was enhanced so you never need to fork or edit the Helm chart. All customization is done through your overrides file, which is typically 50-100 lines. Chart updates apply automatically without reconciling template changes.
Refer to Managing Helm chart updates for details.
Upgrade the database schema before the services start
For RPI v7.8, we recommend a staged deployment:
-
Bring up the Deployment API first.
-
Upgrade the operational database schema.
-
Only then start the remaining services.
Several v7.8 changes add database schema and reference data that the new service code expects to already be in place, including a non-nullable user group column that is read during authentication, new functional permissions, and a cluster monitor task that runs every minute.
Deploying all containers first and upgrading the schema afterwards will complete, but it leaves every service running against the previous schema until the upgrade finishes. Staging the deploy avoids that window, and gives you a checkpoint at Step 6 where a problem is visible before the rest of the estate is running.
Update process
-
Generate or update your overrides using the RPI Helm Assistant. Use the Reference tab to browse available configuration options, or the Chat tab to ask questions about specific features. When upgrading between chart versions, refer to the Migration readme for details on key changes, new features, and any breaking changes.
-
Deploy only the Deployment API on the v7.8 image, with the remaining services not yet started.
-
Upgrade the operational database schema via the Deployment API:
DEPLOYMENT_SERVICE_URL=<prefix>-deploymentapi.<domain>

curl -X 'GET' \
  "https://$DEPLOYMENT_SERVICE_URL/api/deployment/upgrade?waitTimeoutSeconds=360" \
  -H 'accept: text/plain'
-
Wait for
"Status": "LastRunComplete"in the response. You can also openhttps://<deploymentapi-host>/in a browser to monitor the upgrade progress. -
Check the upgrade result as described in Step 6, then deploy the remaining containers on the v7.8 image.
Step 6: Verify the database upgrade
Before you start the remaining services, check the upgrade response and log.
During the database upgrade, RPI automatically removes references to connectors that are no longer shipped with the product. It does this by comparing the deployment's Plugins folder against the plugin assemblies registered in the operational database and removing rows whose assembly file is no longer present. Each removal is audited.
This cleanup prevents repeated plugin-load errors, which can fill the logs and, in some cases, prevent the desktop client from starting.
Check the following in the upgrade response and log:
-
DeprecatedPluginsRemovedreports the number of connector references removed. -
The log does not contain
rpplugin.json not found, which means the cleanup was skipped because the plugin manifest could not be loaded. -
The log does not contain
All {N} plugin assembly rows would be flagged as deprecated; refusing to delete.This safeguard means thePluginsfolder appeared to be empty or incomplete, so RPI declined to remove anything.
The Plugins folder and its rpplugin.json manifest are shipped with the container image, so neither message is expected. If the cleanup was skipped, the upgrade still reports success and the stale connector references simply remain, as they did in v7.7; nothing is broken, but the fix has not been applied. Either message points to a problem with the deployed image rather than to anything in your own configuration, so contact Redpoint support.
After the upgrade, the RPI client also flags any channel or audience still pointing at a removed connector, so that an administrator can repoint or delete it.
Step 7: Validate the upgrade
After upgrade:
-
Confirm application health.
-
Validate:
-
Execution services
-
Message services
-
Connector connectivity
-
-
Run a controlled test campaign.
-
Monitor logs for Redis, queue, or cache-related warnings.
-
Once your maintenance mode buffer has ended, workflows placed in the Queue will be ready to resume once you re-enable them, as described in step 10.
Expected behavior changes
Several v7.8 fixes cause activities that previously appeared to succeed to now report failure. Brief whoever validates the upgrade, so that correct behavior isn't logged as a regression:
-
Offers on a disabled channel now fail the activity. Previously they proceeded. This applies in both Test and Production, and to recurring workflows where the channel was disabled after the first run.
-
LuxSci sends containing a record with an empty body now mark the activity as failed and write a recovery file. Previously they completed silently.
-
Snowflake bulk loads now fail visibly where they previously reported success while silently dropping rows containing NULL numeric or date values.
-
An offer whose configured Sender Email does not match a Cheetah Digital (Marigold) sender profile now fails the send rather than falling back to the channel default.
-
Contentful media is now downloaded and embedded at render time rather than linked, so both preview and delivery fetch from Contentful when the content is rendered.
Step 8: Run the Audience Validation task
Run this before you re-enable workflows.
At each RPI tenant installation, run Config > Audience Definitions > Validate once. This adds the IterationNumber column required by the split and rejoin functionality introduced in v7.8.
RPI tolerates the column being absent, so nothing will fail if this task is skipped, but split and rejoin will not work until it has run. Run it once the services are up and before workflows resume: the task is considerably cheaper to run against a quiet system than one that is already executing campaigns.
Step 9: Complete post-upgrade actions
Some v7.8 changes require an administrator action after the upgrade before the affected feature works correctly. Review each of these against your own configuration.
Channels and offers
-
Confirm every channel in use is enabled.
Offers on a disabled channel now fail the activity rather than proceeding. -
Check Cheetah Digital (Marigold) sender emails.
Verify that every offer with a configured Sender Email matches a real sender profile on the account. A mismatch now fails the send. -
Review email offers set to "Use channel default".
This setting is supported on LuxSci, Salesforce Marketing Cloud, Acoustic, SendGrid, Eloqua, and Cheetah Digital. It still fails validation on the Salesforce Marketing Cloud Data Transfer channel; give those offers an explicit Marketing or Operational purpose.
Connector re-synchronization
-
Run Refresh Catalog on your Snowflake sources.
Several Snowflake data type fixes in v7.8 only take effect when the catalog is re-synchronized. Date and time columns cached before the upgrade retain an invalid form and audiences using them will continue to fail until the catalog is refreshed; VARCHAR columns longer than 1,000 characters and decimal types are likewise only corrected on re-synchronization. -
Re-select the Rebrandly workspace and domain.
If you are upgrading from v7.6 or earlier and have a Rebrandly URL shortener configured, open the adapter, re-select the Workspace and Domain, and save. The domain identifier held before the upgrade cannot be recovered automatically, and URL shortening will not resume until this is done.
Permissions and alerts
-
Grant Interaction - Save where needed.
RPI v7.8 introduces a separate Interaction - Save functional permission. Groups that hold Interaction - Design without Interaction - Build do not receive it automatically, and users in those groups will be unable to save until it is granted manually. -
Set InternalAddress on the Execution Service, Queue Reader, and Node Manager.
Without it, the new excessive-logging monitor cannot reach the services'/metricsendpoints. Subscribe recipients to the new alert. -
Subscribe recipients to the Execution Services - Enabled Status Changed alert.
This alert is new in v7.8 and is off by default.
Step 10: Re-enable workflows
Once you’ve validated the upgrade and completed the post-upgrade actions, you can re-enable your workflows.
If you want to perform any additional validation before re-enabling workflows, you can have RPI up and available to users for a few hours or so of testing to make sure everything is operating as expected before letting your campaigns run. Additionally, you can choose to enable 10-20 at a time, for example, instead of re-enabling them all at once.
Re-activate workflows that were set to Inactive
This is a separate action from reversing Maintenance Mode. A defect fixed in v7.8 could cause trigger housekeeping to revert a workflow to Inactive. The fix prevents this from happening again, but it does not restore workflows that were already affected.
Check for workflows that are unexpectedly Inactive and re-activate them manually.
Rollback considerations
Rolling back to a previous version carries the risk of data loss. Restoring from the backups taken in Step 2 is the reliable path; rolling the binaries back alone does not reverse everything the upgrade changed.
Specifically:
-
Removed connector references are not restored.
The cleanup in Step 6 deletes plugin rows from the operational database. Rolling the binaries back does not bring them back; restoring the Ops DB backup does. -
A renamed LuxSci configuration setting is not renamed back.
If you are upgrading from RPI v7.6 or earlier, note that the upgrade automatically renamesOverrideOHStateTimestampUsingServerTimezonetoLuxsciOverrideOHStateTimestampUsingServerTimezone, preserving its value. If you roll back, re-apply the setting under its original name, or LuxSci offer history timestamps will revert to the provider timestamp. -
Added columns remain.
Columns added during or after the upgrade, includingIterationNumberand the new user group and offer history columns, are not removed. Earlier versions tolerate them, but objects created after the upgrade may lose the new attributes. -
The
rpi_FailoverCachetable is not dropped.
OpsDB-backed cache failover was removed in v7.8, but the table is deliberately left in place for you to remove manually if you choose.